A daily read for AI infrastructure operators.
AI news from the GCC, MENA, open source and China: translated every morning into the real bottlenecks of running GPUs on your own hardware.
What is sovereign AI?
A practical guide to keeping data, models, compute, operations, and governance under organizational control.
8 min
Xing4.0-29B-A4B Moves the Bottleneck to Serving
China Telecom AI released a compact MoE model for local deployment. For operators, the work shifts to VRAM, KV cache, batching, tenancy, and chargeback.
12 min
YC Demo Day points at power and network limits
Atomarine and Dipole Labs highlight two AI infrastructure constraints that smaller GPU operators must manage directly: power and east-west network utilization.
12 min
Nscale IPO plans reset the GPU estate math
Nscale is scaling toward public markets. Smaller GCC GPU operators need a different playbook: utilization, admission control, metering and sovereign operations.
13 min
COFE Tech's AI round tests Gulf inference capacity
COFE Tech's $178 million valuation raises a practical question for Gulf operators: when do agent workloads justify dedicated inference capacity?
11 min
Crusoe funding puts modular AI on GCC agendas
Crusoe's $3.9B raise highlights distributed AI capacity. For GCC operators, the work is scheduling, storage, power, quotas, and chargeback across small sites.
12 min
Qualcomm’s Ultrahuman bet shifts AI toward the edge
Ultrahuman’s $70M round is a signal for GPU operators: more device-side AI changes latency, residency, metering and tenancy assumptions.
13 min
Harvey funding puts inference economics on the operator agenda
Harvey’s $550M raise is a reminder that enterprise AI demand becomes a sustained inference workload, not just a training story.
11 min
OpenAI’s Astra surge is a capacity-planning warning
A consumer AI demand spike can drain inference capacity. GPU operators need queues, quotas, reservations, burst policy and metering before the surge.
13 min
Claude and Cowork convergence raises the tenancy bar
When chat and agentic workspaces share one surface, GPU operators need admission control, metering and isolation before agents crowd out inference.
12 min
Distillation makes VRAM the operator bottleneck
Anthropic's reported distillation findings put attention on smaller models, VRAM fit, tenancy, quota design, and sovereign on-prem scheduling.
12 min
Crusoe’s $3.9B raise reframes GPU estate economics
What Crusoe’s data center and modular AI factory plan means for smaller GPU operators planning power, tenancy, metering, and inference margins.
13 min
Cornelis funding puts GPU fabric waste back in view
Cornelis raised $205M for AI networking fabric. For smaller GPU estates, the test is whether fabric, scheduling and storage lift billable utilization.
12 min
GPU price indices expose GCC placement costs
Open GPU price indices such as Infrabase.ai show that local GCC GPU estates need defensible pricing, utilization, placement and chargeback.
13 min
AI agent security moves into the GPU estate
HiddenLayer’s $100M round and new agent tools point to a practical bottleneck: securing, metering and governing shared GPU fleets.
12 min
AfterQuery and the GCC GPU ingestion bottleneck
AfterQuery’s $3.2B valuation points to a practical issue for GCC GPU operators: data pipelines can starve owned GPUs before compute runs out.
12 min
Nscale’s raise puts tenancy pressure on small GPU estates
Nscale’s planned $3.5B pre-IPO raise shows where AI compute is heading: scheduler depth, chargeback, isolation and utilization discipline.
13 min
YC’s floating data centers point to GPU bottlenecks
Automarine and Dipole Labs are early signals of power, siting and fabric constraints that quarter-rack to few-rack GCC GPU operators must manage now.
12 min
Mistral’s €3B round raises GCC GPU estate questions
Mistral’s €3B sovereign AI round turns model hosting into an operator problem: policy, utilization, quotas and chargeback on local GPU fleets.
12 min
Hy4 preview and DeepSeek Harness stress small GPU fleets
China-origin long-context models make routing, quotas, GPU partitioning and chargeback a control-plane problem for quarter-rack to few-rack operators.
10 min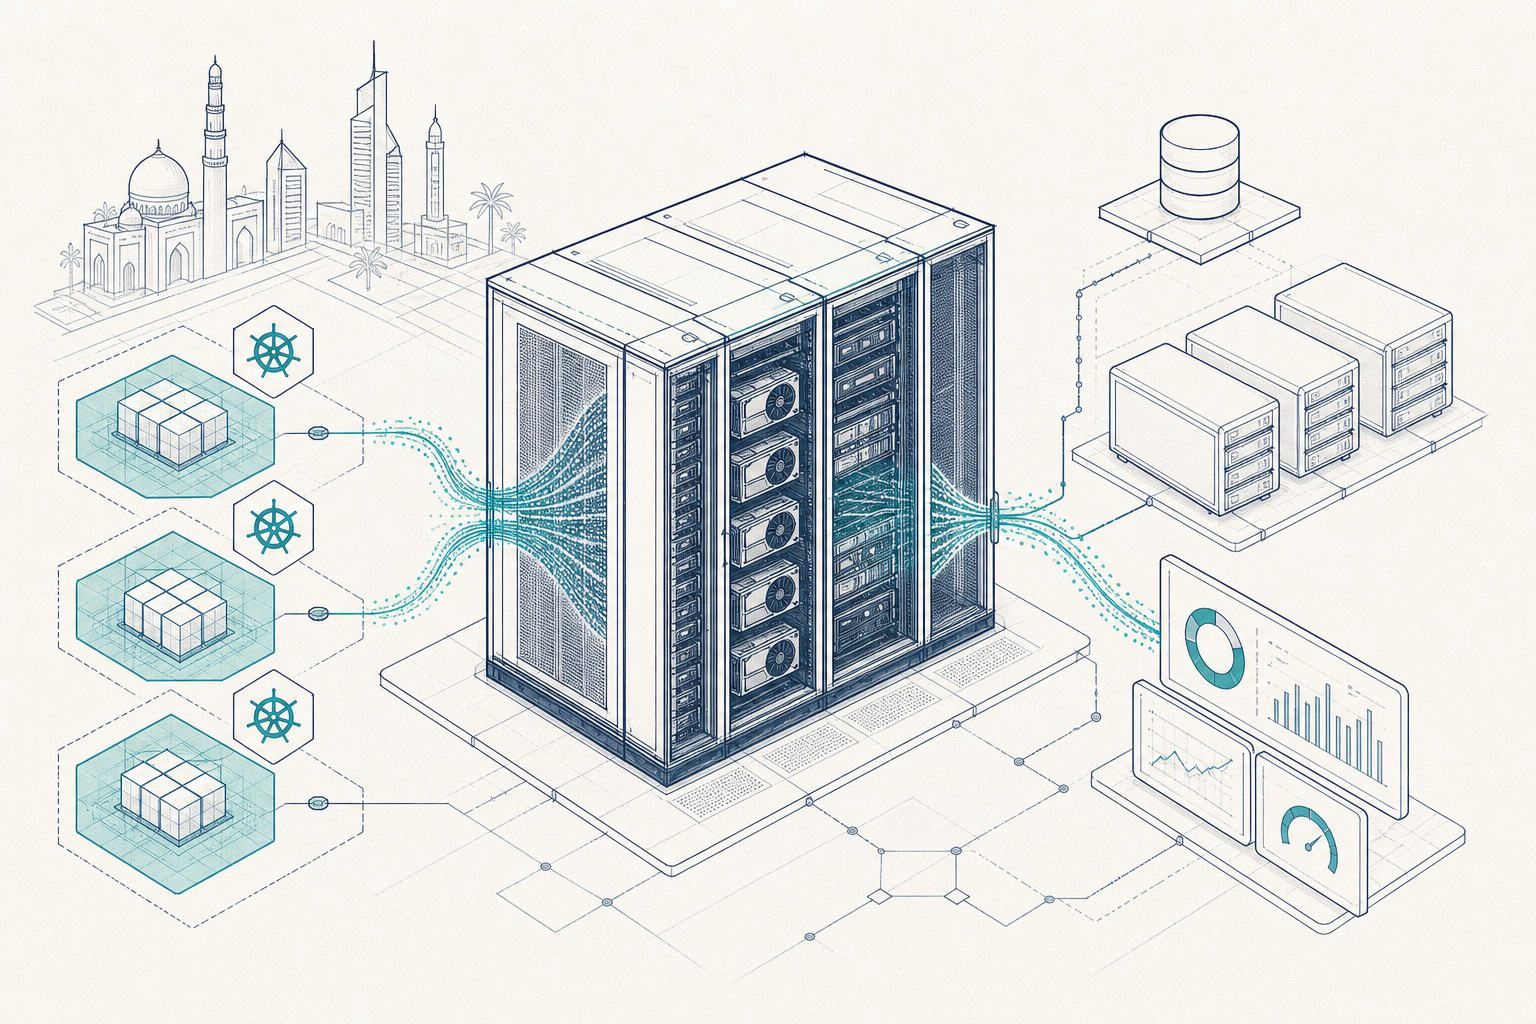
Ox Alpha shifts the on-prem GPU bottleneck to VRAM
Z.ai’s Ox Alpha shows why open-weight reasoning models stress small GPU estates: VRAM, tenancy, quotas, metering and power now matter as much as raw tokens.
11 min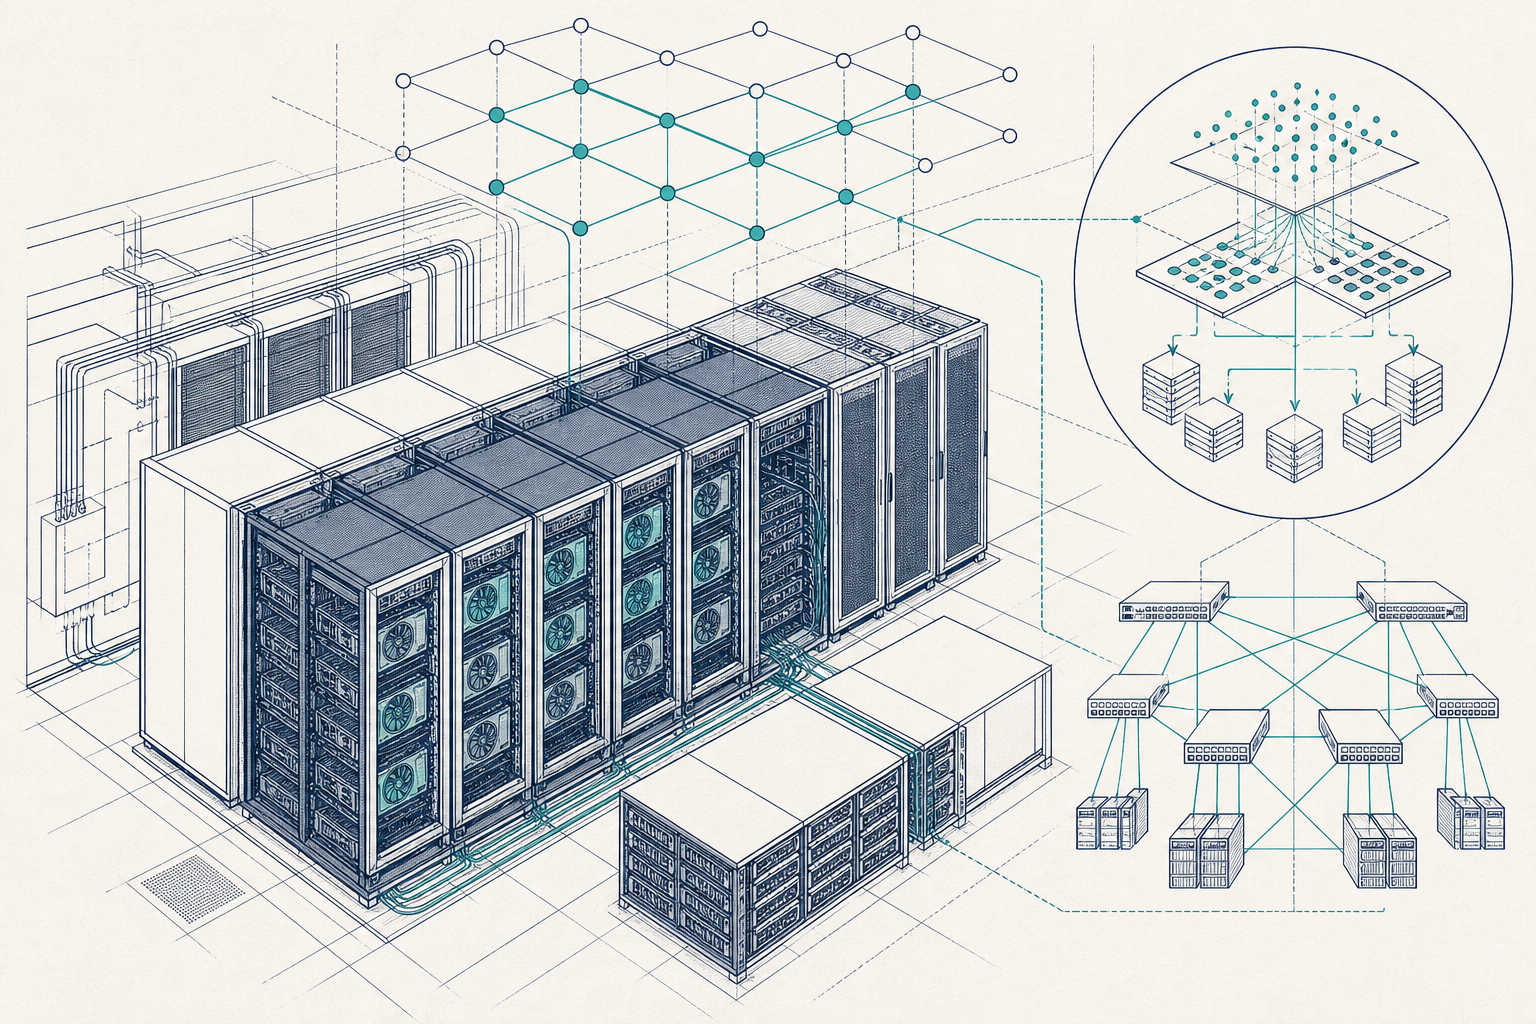
Keenable’s seed round puts retrieval on the GPU plan
Keenable’s $26M seed round is a reminder that AI search and retrieval are infrastructure workloads, not just API calls.
12 min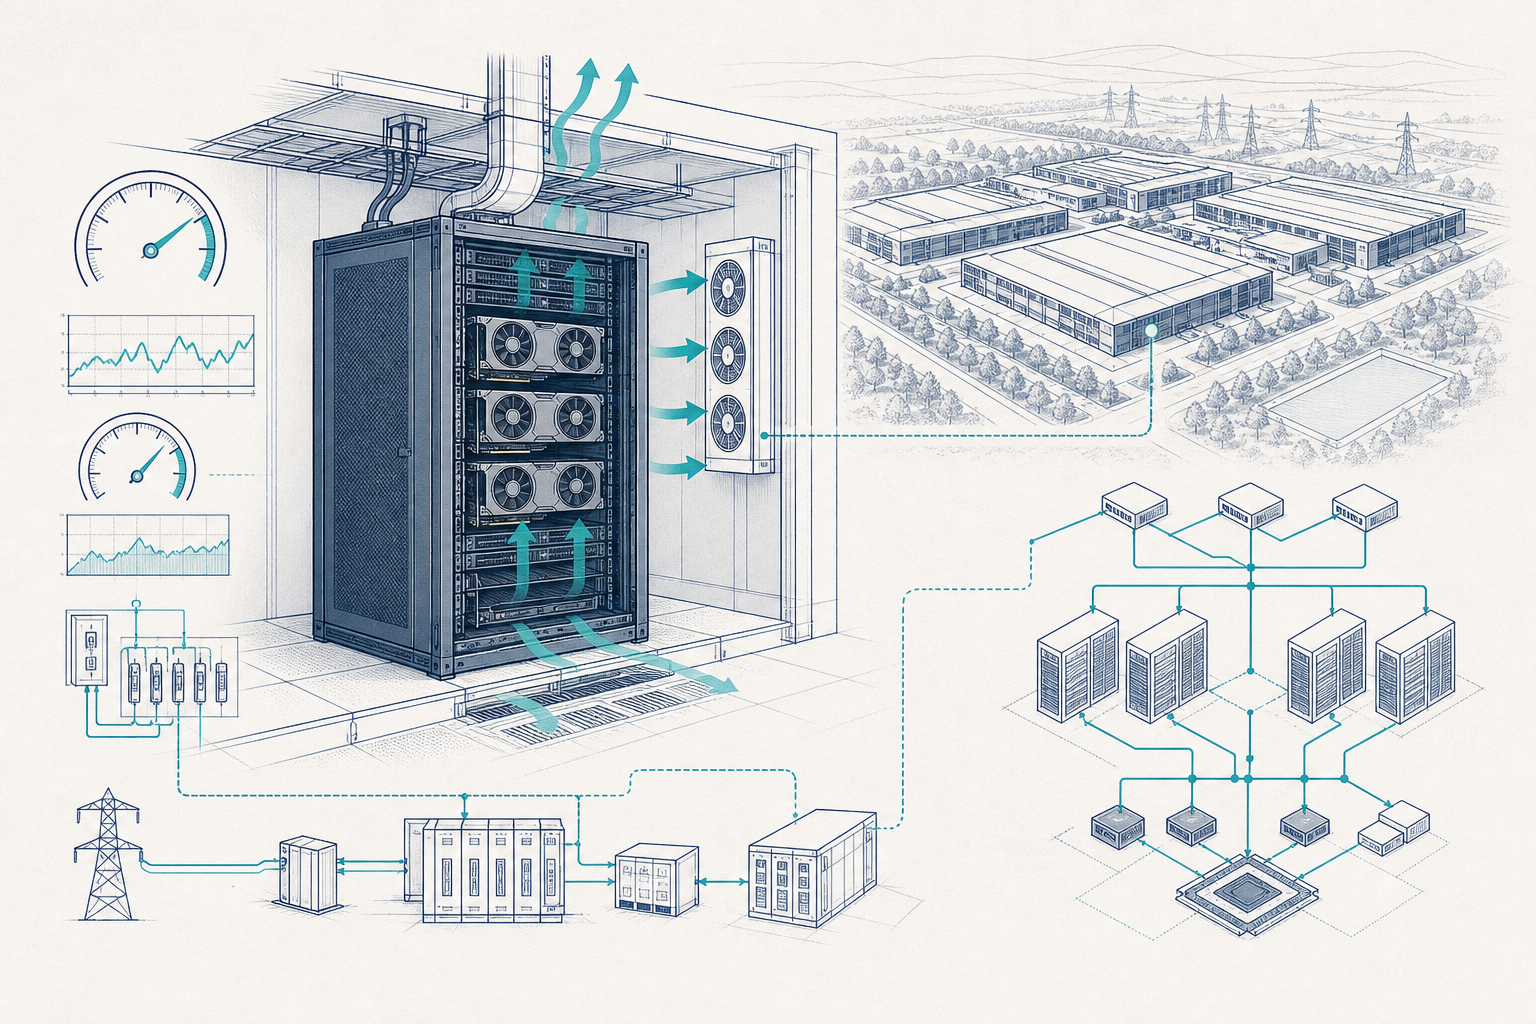
PORTS AI campus puts power economics in view
NVIDIA’s PORTS disclosure shows AI capacity is now a power and cooling problem. Smaller GPU operators need the same discipline at rack scale.
13 min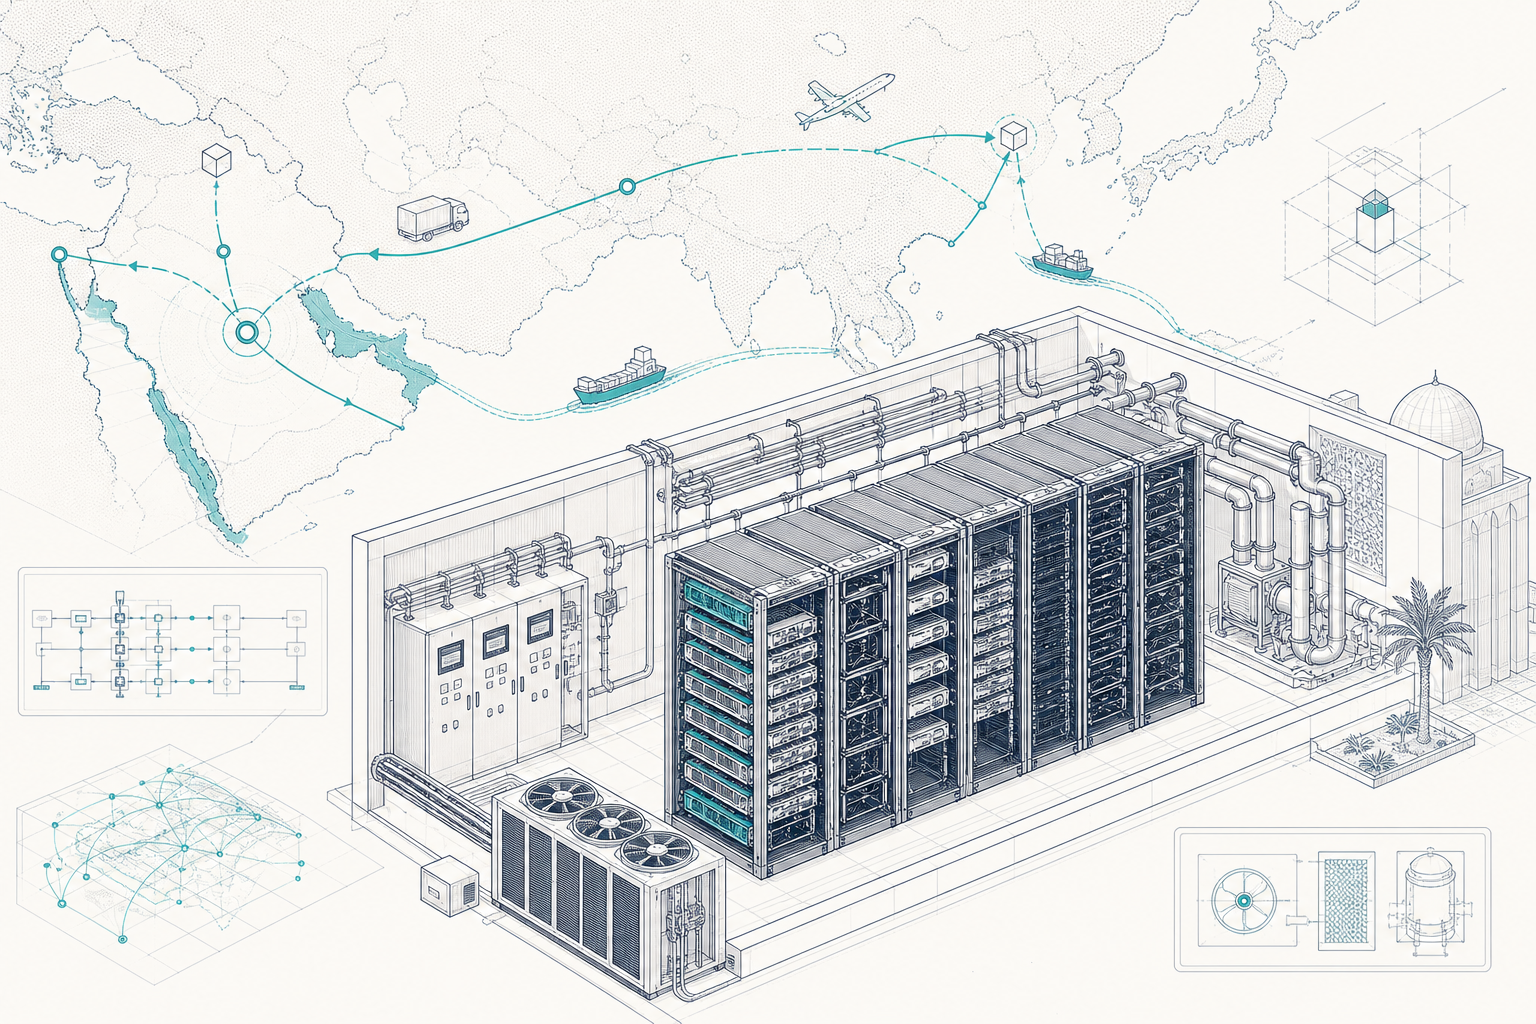
Alibaba’s AI raise and the MENA GPU bottleneck
Alibaba’s HK$80B AI raise points to a practical issue for GCC/MENA GPU operators: supply, hosting concentration, and utilization discipline.
11 min
CGI puts GPU price discovery on the operator backlog
Product Hunt’s weekly ranking shows demand for GPU price indices and routing layers. Small GPU estates now need metering that stands up to chargeback.
13 min
Agent sandboxes will strain small GPU estates
Daytona, Naïve and Keenable point to a practical bottleneck: secure agent tenancy and retrieval traffic, not only raw GPU count.
12 min
COFE Tech puts agentic procurement on Gulf GPU estates
COFE Tech’s pre-IPO round points to a near-term GCC bottleneck: segregating, metering and governing multi-tenant agentic commerce workloads.
13 min
AI capital is moving to power and racks
a16z’s Machine Age fund and Nvidia-linked power bets point to the same bottleneck: owned GPU estates need better utilization, tenancy and chargeback.
12 min
UMAMI LOS exposes the MENA GPU tenancy problem
UMAMI’s LOS launch turns sovereign AI learning into an operator problem: tenant isolation, GPU sharing, metering and national data residency on small fleets.
11 min
HeyBreez and MENA voice AI inference operations
HeyBreez raised $2.5M to build enterprise voice AI. For regional GPU operators, the hard part is low-jitter inference with chargeback and sovereignty.
13 min
nvidia-smi for cluster operators: from CLI to automated fleet telemetry
A field guide to utilization, power and thermals across racks, and where manual polling stops scaling.
12 min